
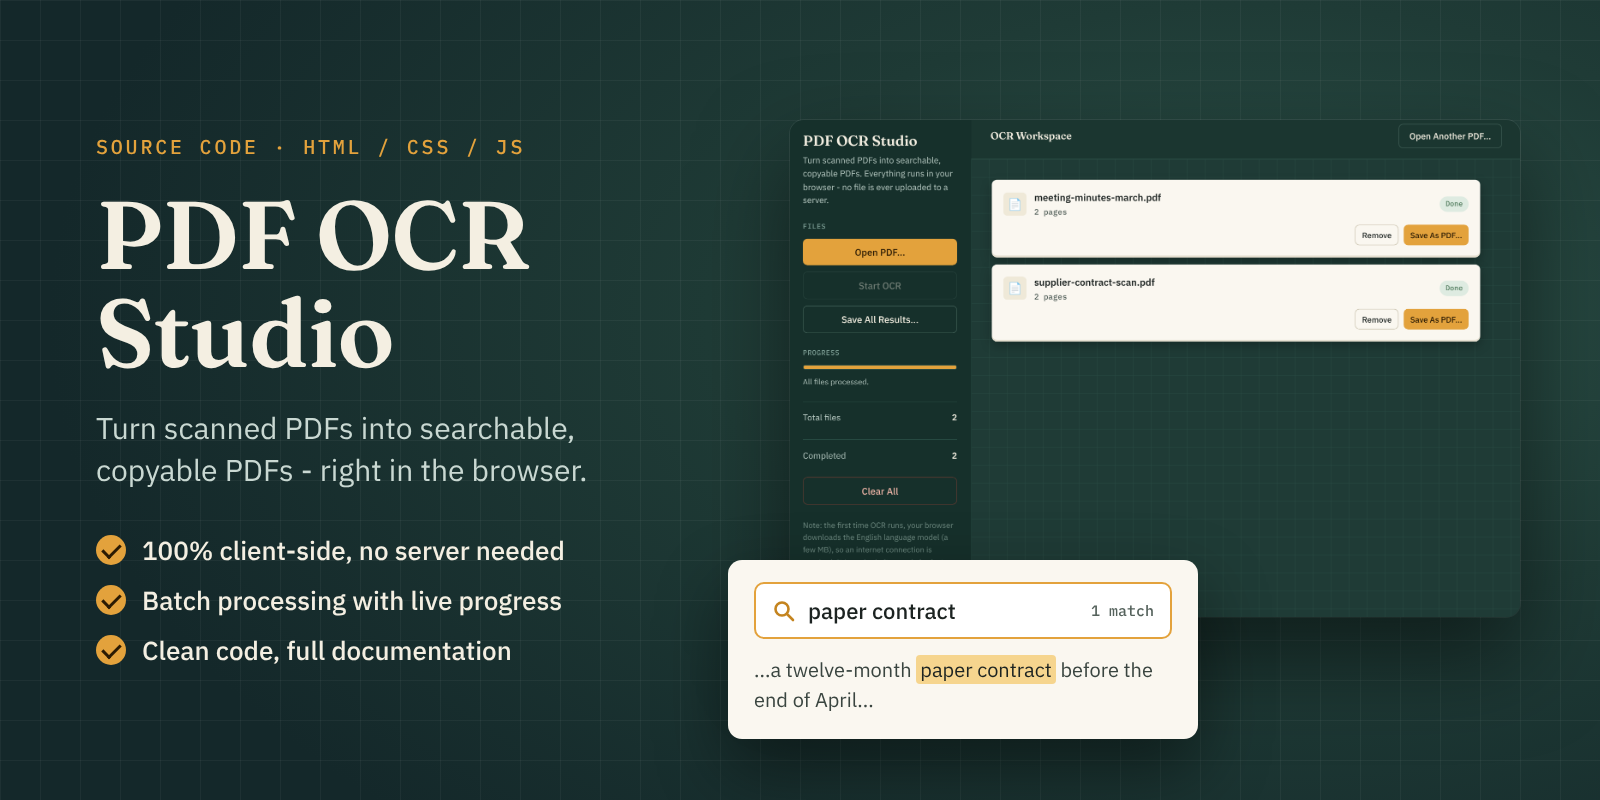
PDF OCR Studio is a ready-to-use web app that converts scanned PDFs into searchable, copyable PDFs, entirely in the browser. There is no server, no backend and no file upload. Every document is processed on the visitor's own device, which makes it a strong fit for privacy-focused websites and products.
The app renders each page, recognizes the text with the Tesseract OCR engine, and places an invisible text layer on top of the original page. The document looks exactly the same, but its text can now be searched, selected and copied.
Why PDF OCR Studio
- Privacy by design: PDFs never leave the user's device, so it is suitable for contracts, invoices and other sensitive documents.
- No backend costs: it is a static web app that runs on any hosting, with no server-side code or database.
- Polished, professional interface: a clean dark-green workspace with file cards, status badges and live progress.
- Complete product, not just a script: includes a built-in usage guide and FAQ section that you can publish as-is.
Features
- 100% client-side OCR
- Batch processing of multiple PDFs, one after another
- Per-file and overall progress indicators
- Drag and drop support
- Save results one by one or all at once, with a native save dialog where supported and a regular download elsewhere
- Original page appearance is preserved
- Responsive layout for desktop, tablet and mobile
- English OCR out of the box, with other Tesseract languages supported through a simple setting
- Built-in guide and FAQ section
- Plain HTML, CSS and JavaScript with no build step
- Easy re-branding through CSS variables
Built with Trusted Open-Source Libraries
PDF.js, Tesseract.js and pdf-lib (licenses listed in the included notices file).
Who Is It For?
- Developers and agencies who need an OCR tool for a client website
- Document, legal, accounting and archive-related websites
- Anyone building a PDF tools collection or a privacy-first utility site
What's Included
- Complete source code (HTML, CSS, JavaScript)
- Documentation covering setup, configuration, customization and offline mode
- Third-party notices, changelog, readme and license file
Good to Know
- Output is a searchable PDF, not an editable document.
- Accuracy depends on scan quality; handwriting is not supported well.
- Password-protected PDFs are not supported.
- The required libraries load from public CDNs by default and can be self-hosted for offline use, as explained in the documentation.
- Requires a modern browser with WebAssembly support.


